
FlowerTune LLM Leaderboard 1위 재탈환
General NLP & Medical 분야 모두 정상 복귀
FlowerTune LLM Leaderboard에서 General NLP와 Medical 분야에 Gachon Cognitive Computing Lab이 다시 최상단에 이름을 올렸습니다.
이곳을 통해 확인할 수 있습니다 -> General NLP Leaderboard, Medical Leaderboard
이번에는 각각의 분야에서 다른 전략을 사용하여 성능을 극대화했기에, 그 과정을 공유해보고자 합니다.
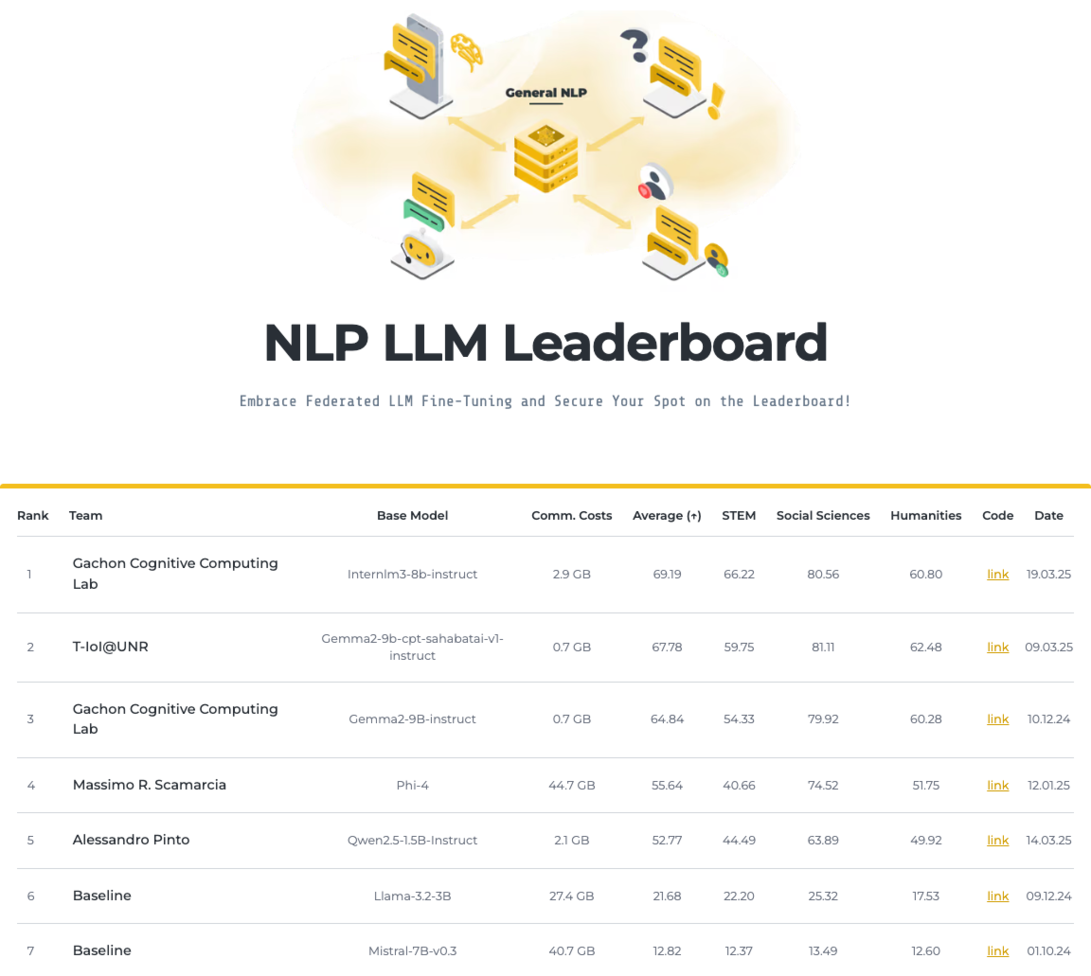
General NLP 분야
- Base Model:
internlm/internlm3-8b-instruct - Fine-tuning 방법: LoRA 기반 파인튜닝 적용
- PEFT 설정:
from peft import LoraConfig

peft_config = LoraConfig(
    target_modules=["q_proj", "v_proj"],
)
핵심 전략
이번 General NLP 제출 모델에서는 InternLM3-8B-Instruct 모델을 선택하고, LoRA를 통해 효율적으로 파인튜닝을 진행했습니다. 특히 q_proj와 v_proj 모듈에 LoRA를 적용한 것이 주요 포인트입니다.
왜 성능이 향상됐는가?
-
InternLM3-8B-Instruction:
InternLM3는 instruction-following에 최적화된 사전학습으로 다양한 태스크에서 강력한 성능을 발휘합니다.
-
q_proj와 v_proj 집중 파인튜닝
Transformer에서
q_proj와v_proj는 Attention 메커니즘에서 Query와 Value에 직접 관여하는 핵심 부분입니다.이곳에 LoRA를 적용해task-specific 정보를 효과적으로 반영하면서도 전체 모델의 안정성을 유지했습니다.
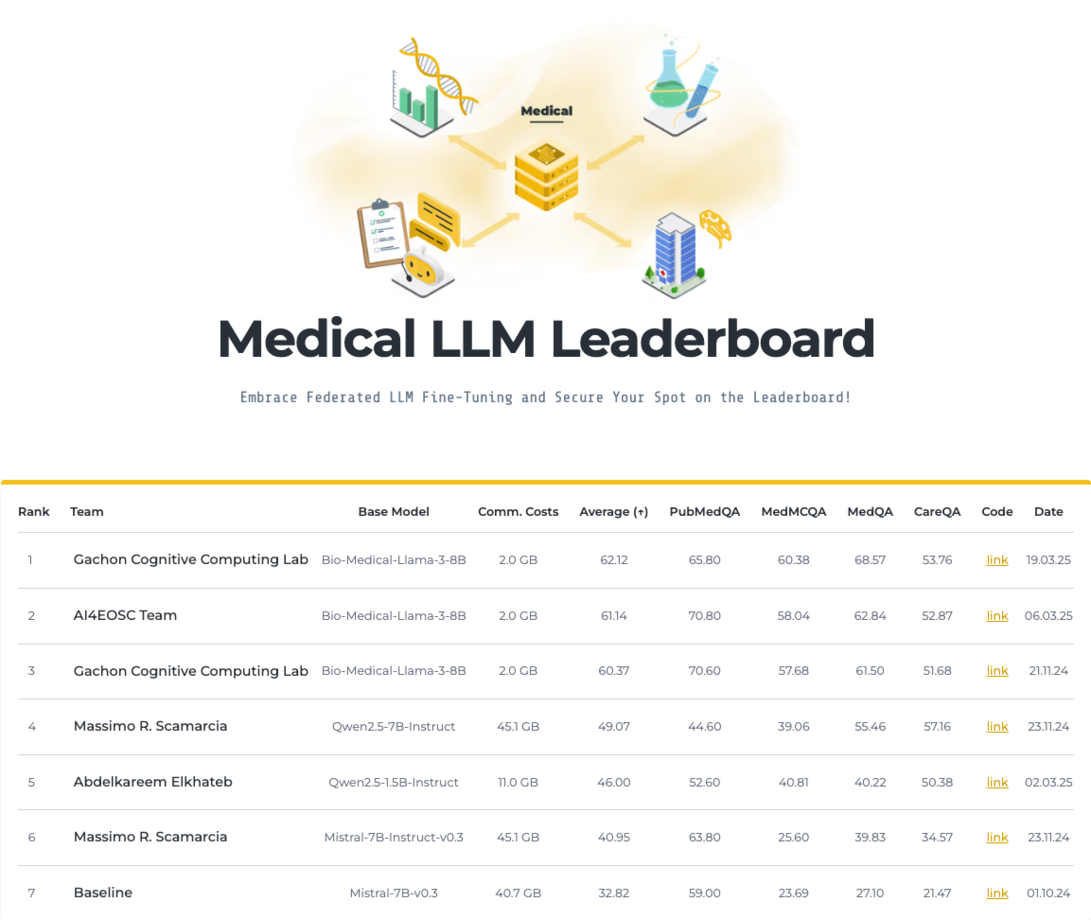
Medical 분야
- Base Model:
internlm/internlm3-8b-instruct - Fine-tuning 방법: LoRA 기반 파인튜닝 적용
- 데이터 포맷팅 방식:
def formatting_prompts_func(example):
    """Llama 3 Style"""
    output_texts = []
    sys_prompt = "You are an expert trained on healthcare and biomedical reasoning."

    for i in range(len(example["instruction"])):
        text = (
            f"<s>[INST] <<SYS>>\n{sys_prompt}\n<</SYS>>\n\n"
            f"{example['instruction'][i]}\n[/INST]\n"
            f"{example['response'][i]} </s>"
        )
        output_texts.append(text)
    return output_texts
핵심 전략
Medical 분야에서는 기존에 사용했던 Bio-Medical-Llama-3-8B 모델을 유지하면서, prompt formatting 방식을 개선했습니다.
왜 성능이 향상됐는가?
-
Llama 3 Instruction 스타일 적용:
<s>[INST]...[/INST]</s>포맷을 통해 instruction과 response의 경계를 명확히 했습니다.이를 통해 모델은 instruction에 이전보다 더 집중해 학습할 수 있었습니다.
-
Domain-specific System Prompt:
"You are an expert trained on healthcare and biomedical reasoning"의료 분야 전문가로서의 역할을 명시적으로 부여해, 모델이 더 일관성 있고 전문가적인 응답을 생성할 수 있습니다.
이번 성과는 모델 선정, 파라미터 효율을 극대화한 파인튜닝, 정교한 데이터 포맷팅이라는 세 축의 조화를 통해 이루어진 결과입니다.
앞으로도 Federated Fine-tuning 환경에서 기술적 완성도와 성능의 균형을 동시에 추구하는 연구를 이어갈 것입니다.
보다 자세한 구현 방식과 실험 세부 내용은 GitHub 리포지토리에 모두 공개되어 있습니다. 관심 있는 분들은 아래 링크를 통해 확인해 주시기 바랍니다.
추가 질문이 있거나 더 자세히 알고 싶으시다면 커뮤니티를 통해 연락해주세요.